Understanding a run
Everything about a run is in runs/<runId>/:
| File | What it holds |
|---|---|
report.md |
The summary to read first. |
events.jsonl |
Every stage and every rejected output, with a reason code. status and the app are built from it. |
plan.json, run.json |
The plan as run, and the run’s state. |
tasks/<id>/ |
Per task: state.json, gate results per round, review.json, and blocked.patch if it was blocked. |
records/ |
One file per model request: role, profile, model id, tokens, time, outcome, and for a failed request the HTTP status and the server’s error text (redacted). Never a key. |
final_review.json |
The review of the whole run. |
Rejections are the heart of the report: every output the harness threw away is counted by reason, such as “edit search text not found”, “typecheck failed”, “depends on code not shown” or “needs a value its type forbids”. Replies that were discarded and retried with thinking off count too. Rejections show where a model struggles, and they are how you compare models.
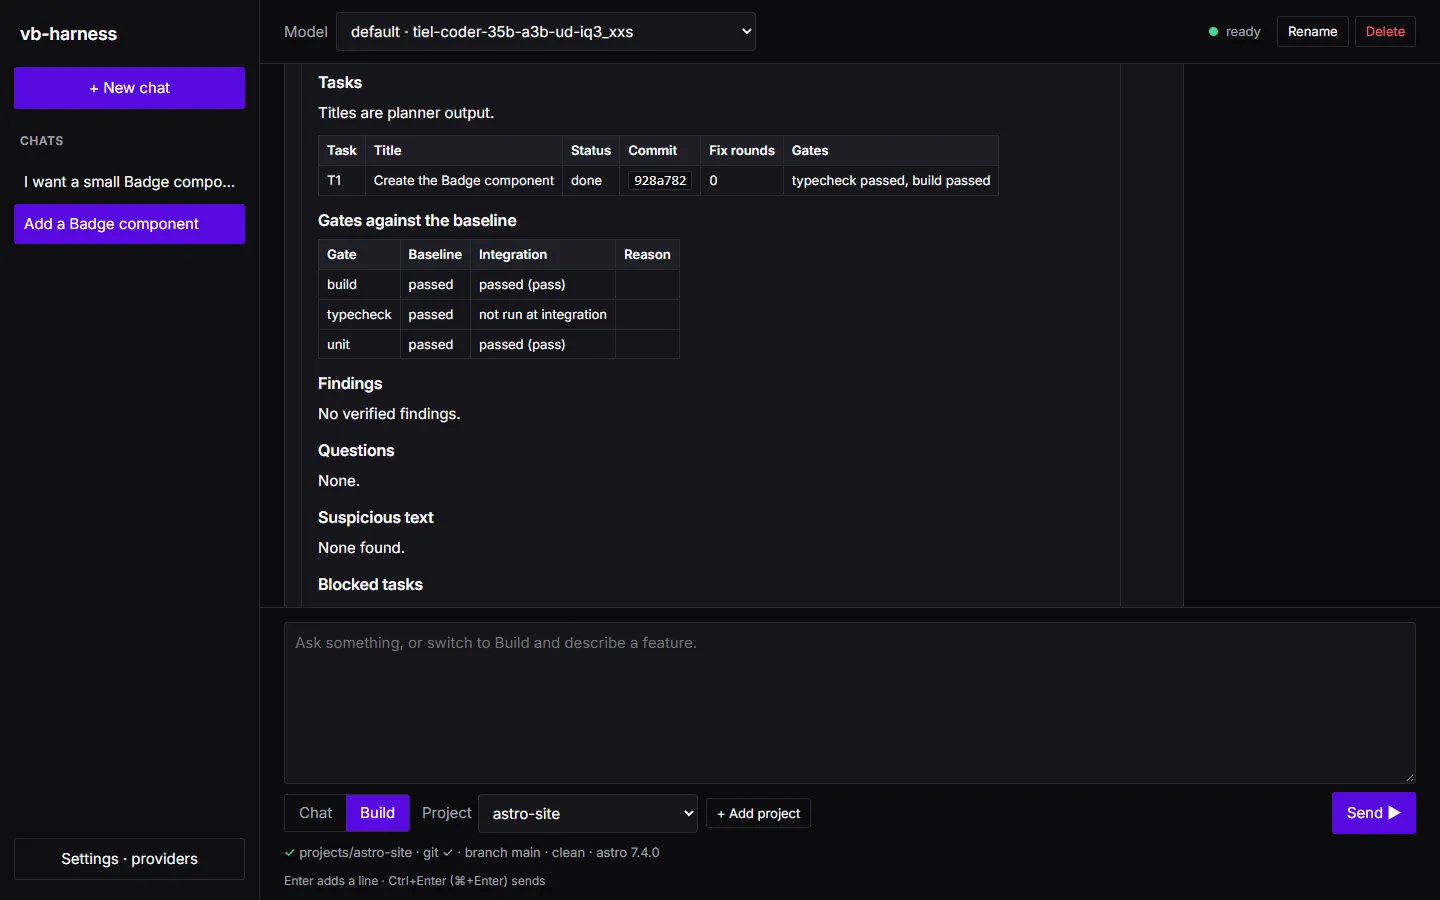
Findings in the report are only claims confirmed by a failing test. Everything else the review raised is under Questions, clearly marked as unconfirmed.
Built by V and Bruno LLC: Astro sites & AI tooling. Work with us →